以太网是否已为 AI 做好准备?证据已在供货
The four sections below each answer it with something already in production, not a roadmap: shipping 800G silicon, a hyperscale Ethernet cluster, the closed utilization gap, and a moving standard. Every figure is sourced to a hardware spec or a named third party.
The hardware is here
Open 800G AI switches are not a preview. They are on the hardware compatibility list and shipping. OcNOS-DC runs on Broadcom Tomahawk 5 and Tomahawk 4 platforms from Edgecore and UfiSpace, the same merchant silicon the rest of the industry builds AI fabrics on, so you keep switch, NIC, and GPU choices open. These are on-chip, shared-buffer switches built for lossless RDMA at 800G.
800G spine and leaf
Edgecore AIS800-64D and UfiSpace S9321-64E / S9321-64EO, the latter with 400G ZR+ coherent ports. On-chip shared buffering for lossless RoCEv2. Both platforms are HCL-listed.
400G leaf
Edgecore AS9736-64D for 400G leaf roles and smaller fabrics, on the same lossless RoCEv2 primitives as the 800G tier, breaking out to 100G and 25G.
Supported as a system
借助 OcNOS Systems,一份 IP Infusion 合同即可同时涵盖 OcNOS-DC 与经过认证的交换机硬件,因此整个 fabric 只需一个 TAC 和一份 SLA。
The scale is proven
The most common objection to Ethernet for AI is scale, and the industry has already answered it in production. You do not have to take a switch vendor's word for it, because the hyperscalers publish their designs.
Meta 在基于以太网的 fabric 上运行 24,576 GPU 的 AI 训练集群。 这是业界的证明:标准以太网如今已在生产环境中大规模承载超大规模 AI 训练。它是回答“是否已就绪”这一问题的参照点:fabric 不是瓶颈。
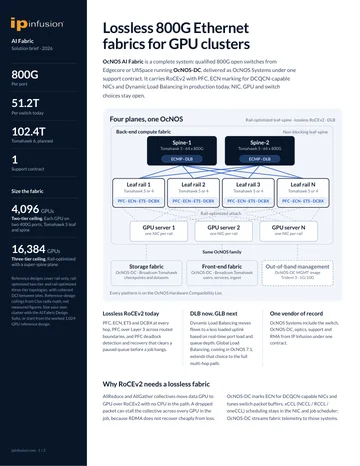
在 OcNOS-DC 上,同样的物理规律也适用于您的构建。双层 Tomahawk 5 设计在每 GPU 800G、1:1 收敛比下可达 4,096 个 GPU。超出后,super-spine 层可扩展至 16,000 个以上。请参阅 AI fabric 拓扑 for the port math behind each tier.
The utilization gap is closed
The old knock on Ethernet was load balancing: standard ECMP pins each large flow to one uplink, so during a collective some links jam while parallel paths sit idle and the sync waits on the slowest link. That gap is now closed on the same switches, and the proof is a hardware feature, not a promise.
How the gap closes. Static ECMP pins each large flow to one uplink; dynamic load balancing rebinds flows on real-time congestion so a well-run AI fabric targets utilization in the 90 percent range on Tomahawk 4 and Tomahawk 5, on the same switches, with no extra uplinks. OcNOS-DC ships DLB on those platforms.
DLB deep-dive →The standard is moving
面向 AI 的以太网并非单一厂商的专有岔路。 Ultra Ethernet Consortium 发布了 UEC 1.0 规范,使以太网传输适配 AI 与 HPC 的规模,并获得芯片、NIC 与云计算企业的支持。IP Infusion 是 Ultra Ethernet Consortium 的 成员 。
UEC 1.0 定义了一种多路径传输,将一条流分散到多条路径上,而不是固定在单个 ECMP 哈希上,这一端点行为运行在支持 UEC 的 NIC 上。OcNOS-DC 如今已在 Broadcom Tomahawk 4 和 Tomahawk 5 交换机上,于生产环境中运行基于 PFC、ECN 标记和 DLB 的无损 RoCEv2。DCQCN 运行在 NIC 上,并对这些 ECN 标记作出反应。请参阅 Ultra Ethernet 深度解析 for how packet spray and multi-path RDMA change the transport.
What OcNOS-DC ships today
Underneath the proof points is a fabric you can turn up now. OcNOS-DC provides the lossless Ethernet fabric that RoCEv2 requires, so your training collectives move GPU-to-GPU over RDMA without loss. DCQCN is the end-to-end loop between the NICs and the switches; the switch role in that loop is early ECN marking. Every primitive below is verified and shipping, not a roadmap item.
PFC
Priority flow control, including over L3, with DCBX and LLDP.
ECN and Dynamic ECN
Early congestion marking, the switch side of the DCQCN loop.
ETS
Enhanced transmission selection to keep RDMA flows ahead.
WRED
Weighted random early detection for queue management.
DLB
Dynamic load balancing with Reactive Path Rebalance and Random Flow.
PFC 死锁检测与恢复
Detects paused-queue cycles and auto-drains before jobs hang.
Buffer tuning
在片上共享缓冲区上进行交换机数据包缓冲区调优。
RTAG7 hashing
Fine-grained hashing for even spread across the fabric.
gNMI / OpenConfig telemetry
Streaming telemetry over OpenConfig YANG for closed-loop tuning.
What is coming next
The items below are roadmap and upcoming-silicon, labeled as such. They are not shipping capabilities today, and none of the figures are IP Infusion performance numbers.
全局负载均衡(GLB)
Extends DLB fabric-wide: spines publish path-quality telemetry back to ingress leaves so routing scores the full multi-hop path.
Latency-based ECN
Congestion marking driven by measured latency, adding to the existing ECN and Dynamic ECN behavior.
LLR, CBFS, packet trimming
链路级重试、基于信用的流控和数据包裁剪,用于在链路和交换机层面进行丢包恢复与拥塞处理。
Broadcom Tomahawk 6
BCM78910 / BCM78914, 102.4 Tbps, 3nm. Announced by Broadcom. OcNOS support planned.
Follow the evidence further
Each proof point above has a deeper technical page. Compare the transports head to head, size a fabric for your GPU count, or read how the lossless behavior is built.
AI fabric 实证常见问题
以太网是否已可用于生产环境的 AI fabric?
在 AI 工作负载上,以太网能否与 InfiniBand 相当?
以太网在 AI 训练中已验证的规模有多大?
OcNOS-DC 目前为 AI fabric 支持哪些功能?
OcNOS-DC 在 Ultra Ethernet(UEC)方面处于什么位置?
现在可以部署开放的以太网 AI fabric 吗?
用 OcNOS 设计整张 AI fabric
从商业论证到端口数量测算,无论您进行到哪一步,都可从此接续。
深入了解,随身带走。
两份简短的技术下载资料,比本页更深入:完整的 OcNOS-DC 数据表和无损 800G AI fabric 架构。
OcNOS-DC 数据手册
表单简短。提交后您的 PDF 将立即在新标签页中打开。
✓ 正在新标签页中打开您的 PDF……
如果未能自动打开,请使用下方链接。
OcNOS 800G 无损 AI Fabric
表单简短。提交后您的 PDF 将立即在新标签页中打开。
✓ 正在新标签页中打开您的 PDF……
如果未能自动打开,请使用下方链接。